PineRAG
Research answers, with the retrieval and timing in view.
An academic question-answering pipeline that ingests papers, retrieves relevant passages, generates grounded answers, and makes latency visible at each step.
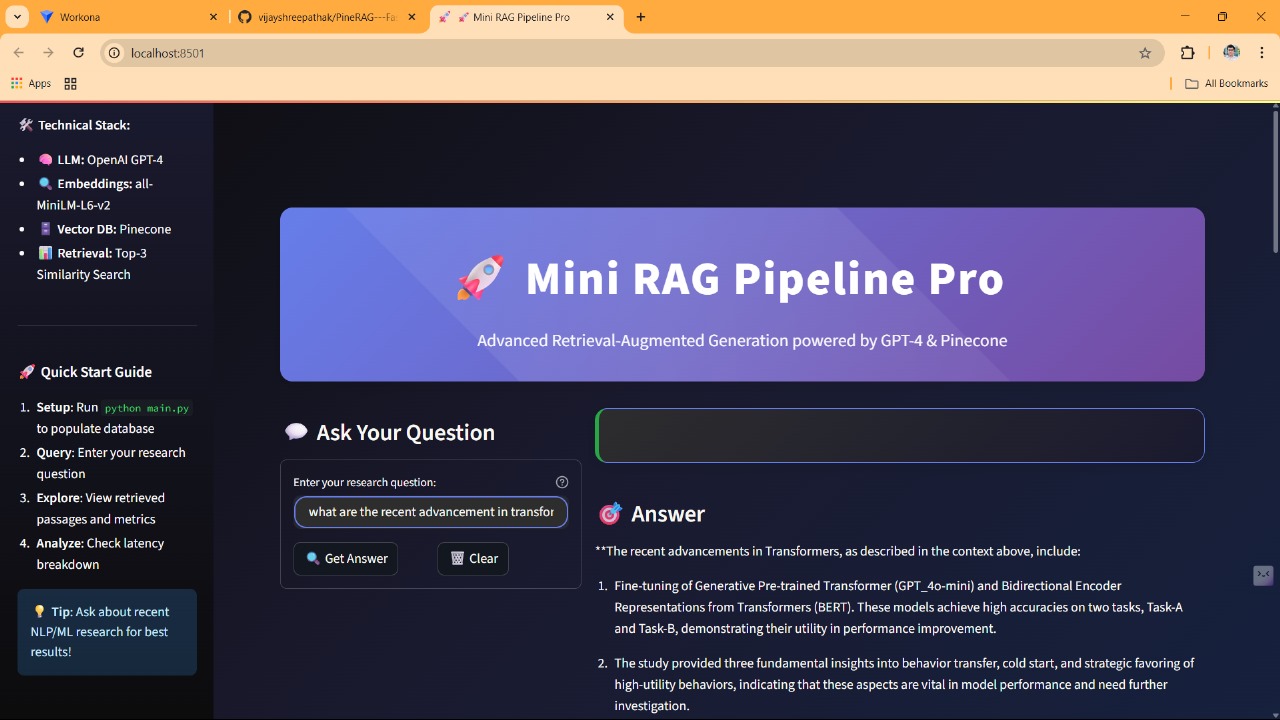
APPLICATION SCREENSHOT · ILLUSTRATIVE OUTPUT
The problem
A RAG response alone hides two important questions: what evidence was retrieved, and which stage consumed the response time?
How it comes together
Paper abstracts are chunked and embedded into Pinecone. Queries retrieve three relevant passages for generation, while the UI displays source passages, similarity scores, and timing.
Follow the flow.
arXiv ingestion and passage-level vector search.
Top-three retrieval with paper titles and similarity scores.
Embedding, search, generation, and total latency breakdowns.
Query and timing export to a CSV log.
Why this approach?
Treat observability as part of the user experience. Source visibility and stage-level timing help explain both the answer and the system's performance.
Hosted-demo availability could not be confirmed during the latest link review. The source repository is available.