Candidate Intelligence Engine
Five sources. One explainable candidate profile.
A deterministic recruiting-data pipeline that turns ATS exports, spreadsheets, resumes, GitHub fixtures, and notes into a consistent profile with field-level provenance.
From records
to a clear picture.
A walkthrough of the transformation engine.
Play here, or open the original video.
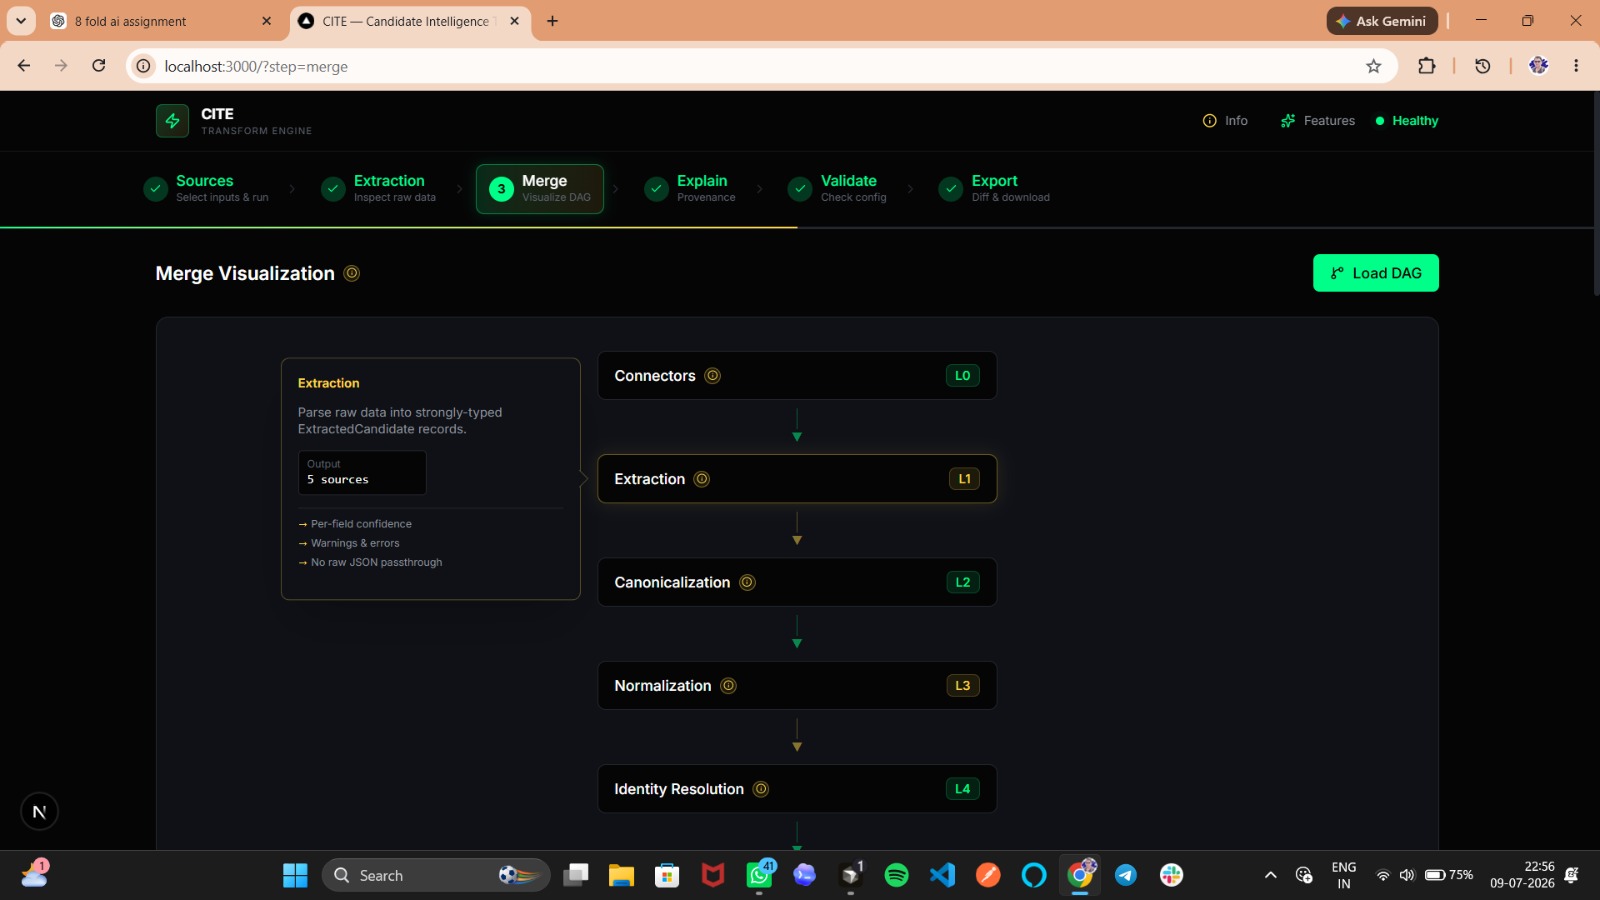
APPLICATION SCREENSHOT · ILLUSTRATIVE OUTPUT
The problem
Candidate information arrives in incompatible formats, with duplicate identities, conflicting values, and no obvious way to tell which source to trust.
How it comes together
Pluggable connectors extract typed records. A normalization and identity-resolution layer feeds a configurable merge engine, then confidence scoring, provenance, validation, and JSON projection produce an auditable result.
Follow the flow.
Five input adapters covering JSON, CSV, resume PDF, notes, and cached GitHub data.
Configurable field-level merge policies and runtime output projection.
A web inspector for extraction, merge decisions, explanations, validation, and export.
CLI workflows and documented unit, integration, and golden-file tests.
Why this approach?
Deterministic rules make the same inputs produce the same output. Source priority and transparent confidence formulas make each merge decision inspectable.
The GitHub connector uses a cached fixture in the documented sample workflow.